Thursday, 28 March 2013

More Maxims for Privacy

I wrote some maxims for privacy a while back, but still I'm looking for that crystalisation of privacy - the "one slider" or "one sentence" that encompasses the foundations, or the basics of privacy.

For the most part privacy comes down to data collection and subsequent usage of that data - the rest is just additions to that. At least if we're concentrating on privacy and not the wider scheme of information management of which I believe privacy is just a sub-speciality, albeit a rather important one.

So, when dealing with information:

"If you don't have a use for it, 
don't collect it!"

For me this sums it up. It links data collection and usage in a way that clearly states that just collect what you need right now; don't even think about the future uses yet. Interestingly I also think that deliberately restricting the data collection right at the start to what you absolutely know you are going to use immediately forces you (the software/system developer) to better focus on the product at hand - "Slow Data" anyone?

In these agile development days however, it is often argued that we'll develop the usages later and collect everything now. How often does this really happen? And, if you really were agile then you'd construct your system initially to do the minimum it needs to and get that out to the customer for their appraisal. If that goes well (or not), then modify as necessary during later stages in your agile development process.

If you're not agile (which apparently is waterfall, though I'm not sure), then you should have worked out what you need and work from there; which again should be self-limiting on the data collection. Surely in a good, fully worked out design you wouldn't be collecting superfluous things?

So, that's it, the essence of privacy as a single sentence; the rest is just layers pertaining to things such as provenance, data retention, purpose, infrastructure etc - that's what makes good information management a whole discipline in itself, of which privacy is one small, but important part.

Thursday, 21 March 2013

Has space exploration become boring?

At the expense of evoking Betteridge's Law of Headlines - obviously space exploration isn't boring - and with Voyager 1 maybe leaving the Solar System, I was wondering what happened to the romance of space exploration.

Does anyone anymore sit up until the early hours of the morning as I did when Giotto encountered Halley, being amazed at Uranus' bizarre collection of moons, fascinated with the existence of nitrogen geysers on Triton, volcanoes on Io; does anyone (other than scientists working at NASA, ESA, JAXA etc) get overly excited these days at pictures from Mercury, Vesta etc?

Does anyone dream of what the Ice Giants explorer might have found at Uranus, or what creatures might live under the icy crust of Europa's ocean?

I remember (pre internet days) desperately waiting for pictures of Neptune, Triton, Miranda, Titan etc to appear in newspapers, books, news broadcasts. Even back in 1992 the joy of connecting to NASA ftp servers to download Voyager and Pioneer pictures of Saturn and it enigmatic, orange cloud enveloped moon Titan on the only Sun workstation with a colour display the university had, over a slow internet link. Watching in fascination as line-by-line the picture was displayed and possibly imagining oneself at JPL watching those raw pictures being received at Earth.

The Register has an article from yesterday on Voyager 1 (yes, still going since its launch in 1977!) which has the paragraph (emphasis mine):

Probably the most-loved survivor of 1970s space optimism, Voyager, has sent back signals indicating that it's left the heliosphere.

Maybe this is it, in the 1970s we were optimistic - there were many missions planned: Pioneers 10 and 11, followed by Voyagers 1 and 2 to complete the Grand Tour of the Solar System; later with the first missions to comets, landers on Venus and Mars.

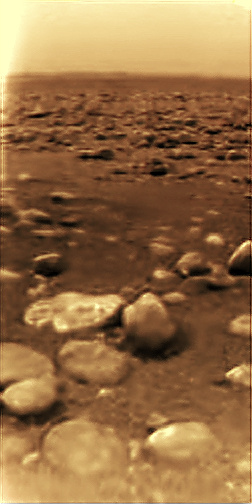
Maybe science just took center stage for a brief moment only to be replaced with the need for fame and appearing on X-Factor? Maybe a picture of the creme brulee surface of Titan from a small lander piggybacked on a probe that made a multi-billion mile tour via Venus, Earth, the Moon, an asteroid or two, Jupiter and finally to Saturn, just don't complete against today's media offerings?

How can you not be amazed by pictures like this - think about what you're looking at and what it took to get those pictures for a moment!


Wikimedia Commons, see: here

On the other hand a grainy picture of Titan from one of the Voyager probes offered mystery and a challenge to be solved - what is under those clouds? - now we get picture of sand grains on Mars. Have we accidentally removed the mystery? Or, have we lost the big exciting picture to a mass audience? A third possibility is that science is either not understood, or just can't complete with a crass, exploitative talent show...

Space exploration in any form is exciting...just listing some of the current probes:
  • Dawn is on its way to Ceres after a successful encounter with Vesta.
  • Messenger has completed mapping all of Mercury's surface and turned up just one or two (or freaking lots!) of major mysteries
  • Cassini is still going strong around Saturn
  • Juno on its way to Jupiter
  • Venus Express still examining Earth's "twin"
  • Numerous orbiters around Mars and not forgetting two (yes TWO!) working rovers on the surface
  • Rosetta is still on its journey to 67P/Churyumov–Gerasimenko.
  • China's moon probe made a detour to visit a near-Earth asteroid
  • Hayabusa returning samples from an asteroid
  • New Horizons still speeds to its all too rapid fly-by of Pluto and its now five moons (incidentally traveling at approx 15km per second or 34000mph)
  • etc etc...
  • oh, not forgetting Voyager 1 and the rest...
Now tell my what that isn't exciting? Maybe our media needs to reacquire its love affair with exploration and science and stop feeding minds with talentless shows...

Monday, 18 March 2013

Privacy not needed?

I'm told that we have no privacy anymore...none whatsoever...and this is why we don't need to review products, services, applications from a privacy aspect. You can argue the same for security and performance...just add memory and cores OK, or, use a longer encryption key?

But actually this touches on many aspects of what is privacy and I'm of the opinion that what privacy offers is the ability to the consumer or user to actively choose what is collected and for what purposes that data might be put.

Overall, however, this places privacy in a very small subset of information management and this is where we really need to turn our focus. Remember the "good days" when databases would be normalised and we worried about the quality of data? Privacy for all its faults and detractors returns us to a point where we need to think about what data we're collecting, how we're storing it and for what purposes it is being used for - that's good information management.

Saturday, 9 March 2013

What has surgery got to do with information privacy?

I'm addicted to books and reading and Amazon knows this - I'm willing to give up quite a lot of my privacy for good book suggestions. I went to Amazon to find a copy of Atul Gawande's The Checklist Manifesto and ended up buying his other two books as well: Better and Complications. I received them two days ago and I've finished Checklist and Better and just starting on Complications - compulsive and utterly fascinating reading about Gawande's insights into his work, surgery and medicine in general.

So why is a computer scientist reading this? Simply because we need more discipline and communication in this field. Surgery has cottoned onto this and is following the safety-critical practices of aviation to improve.

Performing audits, especially those which require a deep look inside a system such as privacy or security is remarkably similar to surgery.

We receive a system for audit, sometimes we get a description and a good idea of what to do, sometimes not. We need to diagnose the system, quite literally probing and performing tests and hoping we don't miss something: an insecurely calculated hash or a hidden transformation of an IP address into a location etc.

We then report back to the system owner with our diagnosis and treatment: hash this, destroy this data, stop collecting x,y and z, add this to the T&C's, add an opt-out, go for a security check etc etc...

We don't always know what we'll find until we open the system up. And like surgery, opening a computer system up is just as painful for the patient as well as the engineer.


Tuesday, 5 March 2013

Category Theory for Scientists

Had to quickly make a note about this as I think David Spivak in his paper (book!) Category Theory for Scientists has written a wonderful guide to what category theory is and how it can be used outside of its topological home. I've always held that the manner of thinking required by category theory provides an incredible toolkit for conceptualising and working with all sorts of structures and concepts, so I'm very, very happy to see something like this.

The only other major work in a similar vein is the deeply mathematical Baez and Stay's paper Physics, Topology, Logic and Computation: A Rosetta Stone.

Weighting Metrics

I'm reading Richard Feynman's book What Do You Care What Other People Think? [1] - a fascinating account of the things that Feynman did and believed in: the power of science and the experiment (there's even a xkcd cartoon about that).

Feynman worked on the Challenger Commission which investigated why the shuttle Challenger exploded and concluded with the discovery of the O-ring failure in one of the solid rocket boosters. One of the most memorable incidents was Feynman's live O-ring in ice water experiment.

However, after dealing with metrics on various issues recently, a paragraph in the book where Feynman discovers the results of a go or no-go decision on the state of the O-rings under cold conditions. There are four named experts and four answers: 2 x no, 1 x yes, 1 x don't know - which effectively splits the vote 50-50 (for some reason don't know = yes).

However Feynman points out that the foremost experts on the properties of the O-rings both stated no and one of the four experts was not present at the original meeting. Taking this into account we get the following:   2w x no, 1v x yes, 1u x don't know, where w > v > u. Simple mathematics returns not a 50-50 split but a split where the no vote would overwhelm (even by a microscopic margin) the yes/don't know combined vote.

Suffice to say here that weighting of the inputs into the calculation here was critical to getting the righ results. This is not to say that finding the weights is not hard, but as we see in the case above even simple ordering would have sufficed.

The metrics are simple, the relevance and weighting unfortunately are forgotten and it is these that really tell you what the metrics mean and how to analyse them.

References

[1] Feynman R. (1988) What Do You Care What Other People Think? Penguin Books. 978-0-141-03088-3

Wednesday, 27 February 2013

Checklists for Privacy Audits

Much of my work are privacy audits of information systems. These vary in nature and context from a quick check to a full dissection, and from client applications to service back-ends, internal systems, cloud deployment etc. Over the years we've made progress in standardising the review both in terms of process and in terms of content along with developing various tools and ontologies for information classification, requirements etc.

One of the most challenging tasks however has been to externalise this knowledge - when you've a small team knowledge is often implicit, but for many reasons including certification (ISO9000 etc) and training new staff documenting the procedures in a form where they can be repeated and understood by others without sacrificing the quality of the review we must externalise what is embedded in our collective team unconscious. Making this simple is remarkably hard - we've certainly been through our fair share of templates, documents, process diagram etc.

Areas such as air traffic control and piloting are well known for their command-response checklist techniques and we've taken much inspiration from these. However the key inspiration for our current ideas actually came from the WHO's Surgical Safety Checklist which aims to provide a simple, high-level checklist for surgical procedures without compromising the context in which the checklist is employed. This latter aspect rings especially true for us in that our context of review changes dramatically between audits as do individual surgeries. Here's our version:


We've remained true to the WHO's version (why change something that works?) with the three high-level stages, two of which emphases the necessity of getting the scope, context and reviews made properly. The middle section - the operation if you like - preceded by a time-out in which we ensure that each member of the privacy audit team works properly together and have a common understanding of what is required. Note the emphasis at the end of evaluating the review and the effectiveness of our procedures - this is critical in bettering how our work is executed.

An accompanying manual in the same style as the WHO's Surgical Safety Checklist Implementation Manual is under construction and in test. This we aim to address not just the process but the roles and responsibilities of the case coordinators, the "operating team's" (including individual members) roles, management and, importantly, the R&D or owner of the system being investigated. Never forget about the customer especially as privacy reviews tend to be quite deep and invasive both in time, information needs and recommendations, Many development teams do see such reviews as not effective use of their time and taking them away from their primary job of developing software.

Now there are many existing checklists for privacy - some detailed, some more process oriented, some technical, some more legal in nature - but consolidating and standardising without compromising the contexts in which these are executed is the issue. This I expect is the guiding principle behind the WHO's checklist which itself has been proven to work effectively.

It is my belief that the best practices from safety-critical system development need to be deployed in the systems we are building through development techniques, methods and processes. I consider good information system management (through privacy principles) to be safety-critical in many senses.

* * *

Compulsory Reading: Atul Gawande. The Checklist Manifesto.

Thursday, 21 February 2013

Some thoughts on Gamfication


It seems everyone is talking about gamification: the idea that any service can be turned into a game, reasoning that through reward and bargaining mechanisms a user will interact more with that given service for presumably greater rewards.

Although gamification seems to be the current zeitgeist, the idea is relatively old and the new part is this explicit in the customer-server interaction and inherent in the development process of applications and services. 

Many of the underlying concepts of gamification come from Game and Economic Theories such as those extensively researched and developed by Nash, von Neumann and. It is the principle behind the usage of store cards, air miles, nearly every loyalty scheme and most recently (in internet terms) the idea behind the “free” service. 

Despite gamification now coming to the fore, gamification is already relatively well established in many areas including privacy, although not as explicitly as currently being suggested.  For example you get your social networking (or blogging provision!) for free by giving up your privacy – you get a free service (and advertisements) and the service provider gets your behavioural profile. 

We can simply demonstrate this aspect of gamification in privacy by constructing a small normal form model using Game Theory techniques. Consider the payoff  between a customer and some service – if the customer registers with that service then they obtain an enhanced service:

Service
Basic Enhanced
Anonymous Random advertisments, No personalization, No identification of user, No targeting, No profiling 0
Customer Pseudo-Anonymous Random advertisements, Some session provisioning, Pseudo anonymous tracking Limited profiling – non traceable 0
Registered/Identified 0 Targeted advertising Full user experience, Customisable, Profiled

The difficulty here is assigning values to the sets of features available versus the data collection. In the above example disabling cookies has probably better payoff than leaving them enabled, primarily at the expense of the quality of data being collected by the service versus the consumers’ privacy. If we consider what the enhanced service might provide then the fact that the consumer is being profiled is outweighed by the advantages of the enhanced service. Certainly in the above, it is in the service’s interests to ensure that the benefit to the consumer outweighs any privacy (or other) concerns.

Payoff matrices for services such as Facebook, Google, Skype, Amazon etc, can be similarly constructed? It might just be that a well-defined payoff is what is contributing to those services’ popularity when put in the context of privacy.

Things get more interesting when services are combined. For example would letting Amazon provide Ikea with your purchase details being a step too far regarding personal privacy? Maybe Amazon should consider teaming up with Ikea… 10% discount vouchers on book cases for every 20 books bought…as long as you tell Amazon your Ikea Loyalty Card number. Just no recommendations for books on interior decorating please!

To further strengthen the gaming link, in the above the customer is also presented with a challenge in optimizing the reward – what is the cheapest way of getting a cheaper bookcase?

It might also just be that gamification becomes one of the drivers behind improving the quality of Big Data. The more “points” your score using a service, the better the quality of the profile and better service. The question here then becomes are we as individuals (or even as collectives) that interesting or for that matter, are we as consumer that discerning in the content from service providers and the back-and-forth bargaining? Do we care enough to be interested in playing the service improvement game?

Will gamification improve on the experience for the consumer and turn us all in to marketers of our own information?  Will recasting your service as a game lead to greater popularity, more consumers and success? 

What interests me, assuming the above answers are positive, is then how to do this through the embedding the economic principles of gamification inherently into the system design.

References

Tuesday, 5 February 2013

Deconstructing Privacy

Some very constructive comments after my previous posting on the naivety of privacy - thanks to all who participated. So to address this problem that we are often talking cross purposes and without any common frame of reference we need to first take a look at in what terms we're framing privacy [of information systems].

Typically we see that privacy is addressed or framed in seven broad areas:


Each of these areas most certainly overlap but we have the difficulty of switching between these frames. For example, it is often the case that if we have great system security, then privacy is of little concern because we've addressed the problem of data leakage; however we haven't addressed the problem of data content because this is largely irrelevant to security. Similarly if we have great access control we don't have to worry about the data getting into the wrong hands? Or possibly that if we've presented the user with the necessary consents then all is fine?

If we firstly deconstruct each area and examine how each views privacy, then attempt a cross-referencing exercise between these, then we might actually have a basis for constructing, at least a framework for a common terminology and semantics.


Friday, 25 January 2013

On The Naivety of Privacy

Recent events regarding privacy and the internet have left me wondering if we are being somewhat naïve. We are starting to see a slew of new laws, strategies and technologies for protecting our privacy in what is effectively a public space. The end-user however is not, as far as I can tell, really getting the benefit of this - indeed if anyone is it is the emerging privacy-industrial complex [1] as some have written.

It is utterly naïve to believe that laws, strategies, intentions, grand speeches, certifications, automatic filtering, classification iconography and so on make for better end-user privacy. The more we do this the more confused we become, and simultaneously we lose sight of what we're really trying to achieve. Spare a thought for the poor end-users.

There is a great deal that is misunderstood or not known by privacy advocates about how the internet, computers and information systems work - I fear in a lot of cases either some don't want to understand because it takes them outside of their comfort zone, or the semantic gap between the engineers and the legal/advocacy side is too great and that bridging this gap is extraordinarily difficult for both parties.

I worry about our lack of formality and discipline, possibly in equal quantities. We – the privacy community – lack these aspects to really understand and accept the fundamentals of our area and how to apply this to the information systems we are trying to protect. In some cases we are actively fighting against the need to scientifically ground our chosen area.

We must take a moment to think and understand what problem we are really trying to solve. The more philosophical works by Solove and Nissenbaum address the overall concept of privacy. I'm not sure that the implications of these are really understood. Part of the problem is that general theories of information [2] are very abstract and obtuse when compared with the legal views of the above authors, and we've done very little to tie these areas together to produce the necessary scientific formalisation of privacy we need.

As an example, the Privacy by Design (PbD) manifesto is being waived by many to be the commandments of privacy and following these magically solves everything. This only leads to “technical debt” and greater problems in the future. Often we find the engineers, R&D teams and the scientists excluded from, and outside of, this discussion.

I think we're missing the point what privacy really is and certainly we have little idea at this time how to effectively build information systems with inherent privacy [3] as a property of those systems. I have one initial conclusion:


WE HAVE NO UNDERLYING THEORY OF PRIVACY


We have no common definitions, common language, common semantics nor mappings between our individual worlds: legal, advocacy and engineering. Worse, in each of these worlds terminology and semantics are not always so well internally defined.

When an [software] engineer says “data collection”, "log" or "architecture", these do not mean the same to a lawyer or a consumer advocate. Indeed I don't think these terms semantically map even remotely cleanly – if at all - between these groups.

A set of PowerPoint slides with a strategy, a vision, a manifesto, good intentions, project plan or a classifications scheme mean very little and without some form of semantics are wasted, token efforts that only add to the complexity and confusion of a rapidly changing field.

We desperately need to address the problem that we must create a way of communicating amongst ourselves through which all of the internal factions within the privacy community can effectively understand each other's point of view. Only then might we even have a chance of realistically and effectively addressing the moving target of privacy issues facing end- users and businesses that rely so much on the interchange and analysis of information.

The problem with formally (or rigorously) defining anything is that it has the nasty tendency to expose holes and weaknesses in our thinking. Said holes and weaknesses are not entirely appreciated, especially when it challenges an established school of thought or a political or dogmatic balance [4].

The privacy community is constantly developing new laws and legal arguments, new sets of guidelines, manifestos and doom scenarios while the engineers are trying to address these often inconsistent and complex ideas through technical means. From the engineering perspective not only we are internally exposing flaws in database design, information system architecture and user experience but also the mismatch between engineering, legal, the world of the consumer advocate and ultimately a company's information strategy.

An information strategy needs to address everything from how the engineers develop software to how you want your company to be perceived by the consumer. How many information strategies actually address the role that information plays in a modern, global consumer ecosystem where the central concept is the collection and processing of user information? Of those, how many address the engineering and scientific levels of information?

We must take a serious retrenchment [5] step and look back at what we have created. Then we need ruthlessly carve away anything that does not either solve the communication issue within the privacy community or does not immediately serve the end-user. Reemphasizing the latter point, this explicitly means the end-user values, not what we as a privacy community might perceive to be valued by the end-user.

We must fully appreciate the close link between privacy and information, and that privacy is one of the most crosscutting of disciplines. Privacy is going to expose every single flaw in the way we collect, manage, process and use information from the user experience, as well as the application and services eco-system, and even the manner in which we conduct our system and software engineering processes and information governance. The need to get privacy right is critical not just for the existence of privacy as a technical discipline in its own right (alongside security, architecture, etc) but also for the consumer and the business.

The emphasis must be placed on the deep technical knowledge of experts in information systems – these must be the drivers and unifiers between the engineers, the lawyers, the advocates and ultimately the users. Without this deep, holistic, scientific and mathematical foundation we will not be able to sufficiently nor consistency address or govern any issues that arise in the construction of our information systems at any level of abstraction.

If the work we do in privacy does not have a scientific, consistent and formal underpinning [6] that brings together the engineers, lawyers and advocates then privacy is waste of time at best and deeply destructive to the information systems at worst.

Without this we are a disjointed community caring for ourselves and not the business or consumer and privacy becomes just a bureaucratic exercise to fulfill the notions of performing a process and metrics rendered as meaningful as random numbers.

* * *

PostScript:

Via Twitter I came across a talk given by Jean Bezivin entitled "Should we Resurrect Software Engineering?" presented at the Choose Forum in December 2012. Many of the things he presented are analogous to what is happening in privacy. He makes the point a number of times that we have never addressed the missing underlying theory of software engineering and how to really unify the various communities, fields and techniques in this area. Two points I particularly liked was that we concentrated on the solution (MDE) but never thought about the problem; the other point is the use Albert Camus' quote

<< Mal nommer les choses, c'est ajouterau malheur du monde >>
[To misname things is to add misery to the world]
A subtle hint to getting the fundamentals right: terminology and semantics!


Notes

[1] #pii2012: The Emergent Privacy-Industrial Complex

[2] Jerry Seligmann, Jon Barwise (1997) Information Flow. Cambridge University Press.

[3] I like the idea of privacy being an inherent construct in system design in much the same way that inherent safety emerged from chemical/industrial plant design

[4] A blog article discussing “mathematical catastrophes” – two that come to mind are Russel and Frege and also Russel and Gödel. Both related but the latter’s challenge to the mathematical school of thought was dramatic to say the least.

[5] A formal retrenchment step in that we not just start again but actively record what we’re backtracking on. Poppleton et.al. constructed a theory of retrenchment for software design using formal methods; the same principles apply here.

[6] If you’re still in doubt just remember that whatever decisions are made with respect to privacy, there’s a programmer writing formal, mathematical statements encoding this. Lessig’s Code is Law principle.


Wednesday, 23 January 2013

Kubler-Ross and Getting Ideas Accepted

When discussing new or challenging ideas, or even anything that challenges or even questions the existing schools of thought (or business process!) there is often much "push-back" with responses such as "that'll never work", "impossible" etc...sometimes even when confronted with the evidence and demonstration.

Dealing with this is often soul destroying from the innovator's perspective and getting past this is 90% of the challenge of getting new ideas and view points accepted. So having a mechanism to understand the responses would be useful. I think the Kubler-Ross model might be useful here to examine people's responses.

The model itself was developed for psychologists to understand the process of grief. While the model has sparked some controversy, this does not detract from the basic principle of the model. The model consists of five sequential stages:
  1. Denial - "we're fine", "everything works"
  2. Anger - "NO!"
  3. Bargaining - "Ok, so how do you fix this?"
  4. Depression - "Why bother...?", "Too difficult"
  5. Acceptance - "Let's do this!!!"
When applied to challenging ideas, the person rejecting those ideas has to proceed through the above stages - and the challenger has to also acknowledge this and work within this.

Let's say we have a process and metrics for some purpose - the process is complicated and dogmatic, the metrics measure some completion rate but not effort or compliance. A challenge to this might be met with the following responses:
  1. Denial - the process works! No-one has complained! We have metrics! We're CMM Level 3!
  2. Anger - Why are you complaining? We don't need to change!
  3. Bargaining - OK, we'll consider your ideas and changes but we're not promising anything. Can you come up with a project plan, budget, strategy, PowerPoints etc...?
  4. Depression - OK, there are problems, but we can't deal with them. It's too late and complex to change. Let's create a project plan, strategy and vision. How can we ever capture those metrics?
  5. Acceptance - You're right, let's run with this
Actually the last state - acceptance - probably works very well in a more agile environment, but agility requires both a deep and holistic and ultimately an approach grounded in the theory of the subject at hand. Do not underestimate getting management support either, and conversely as a manger giving real support is similarly critical.

This model must be used in an introspective and reflective manner to ensure that you as the originator and presenter of the idea do not fall into the trap of stages 1 and 2 yourself. Understanding your reactions in the above terms is very enlightening regarding your own behaviour.

If you do reach stage 3 in the discussions then this is time that you need to be absolutely sure in how your idea works, what the flaws are and how it integrates and improves what came previously. At this stage you have the chance to get everyone on board but after this however it is extremely difficult to turn people to your idea.

Stage 4 is depression all round, you will probably have accepted many changes to your idea and let go of some cherished ideas. Worse is that you've probably challenged the existing school and dogma to such a degree you are going to get a lot of "push back" on the ideas. In some respects this is where ideas do die either "naturally" or through "suicide" to use some dark terminology. To get through this stage you need to be the supporter of everyone. Indeed emphasis on the previous school of thought as being the catalyst to the newer ideas is critical to get through this; after all, wasn't it the previous systems that sparked the need for change in the first place?

Stage 5 is requires real leadership of the innovation and building of the team to carry this forward. Like it not, teamwork and ensuring that everyone, even the detractors, have a voice is critical. Sometimes your challenge might free some of the original detractors out of their earlier beliefs - this can come as quite a relief to these people and offer them badly needed, new challenges and purpose.

There are many more things one could write on this and there are many books and theories on how to manage innovation and invention elsewhere. The idea here was to relate some experiences with the Kubler-Ross model and understand things in that context, which personally I've found to be a very useful tool.

Monday, 7 January 2013

Tutorial: Tracking

Tracking and anonymisation are two critical aspects of information privacy and often quite misunderstood. We established what is meant by Personally Identifiable Information (PII) earlier but now I wish to progress a little further and discuss identifiers, tracking and anonymisation of data sets.
  • A data set is a collection of records containing information. 
  • A record is usually made of up of a number of individually named fields, though it could be a more complex structure such as a graph or tree for example. 
  • Each field contains some data from something as simple as a binary value, to a name, a number, a time-stamp, a picture or a video etc.
  • These fields are usually typed, for example: string, boolean, integer, VARCHAR, blob, media, something from the dc: namespace etc. However a field containing, say, a string could be further interpreted as a telephone number or a name. Some typing systems make distinctions such as a field storing a string to be interpreted as a telephone number explicit, others this is left to the interpretation by the reader.
  • Some fields in the data set's records are used to identify either aspects of that record, to correlate records together or to link to some external data. These fields we term identifiers.
Tracking is the ability to correlate information; often made in conjunction with some criteria such as a temporal, device or user identity dimension. The correlation is made according to one or more fields which act as identifiers, for example, user ID fields or IP addresses. The point is that we have a consistent identifier (or key) over the sets of data that we wish to relate or consider together. For example, given the following data set collected from some music service:

Key UserID Artist
1 Alice Queen
2 Alice Queen
3 Bob Rush
4 Bob Rush
5 Eve Spice Girls
6 Alice Queen
7 Bob Genesis
8 Eve Metallica

From this log we might want to track user behaviour to understand what music a particular user of our system likes listening to: we can see that Alice likes Queen, Bob is a fan of progressive rock and Eve has varied taste in music. This is possible because we have a consistent identifier (UserID field)  that any two instances of an entry refer to the same entity - the user. Furthermore the Key field allows us to make a distinction between two instances containing the same information which enables us to count individual entries: Alice played three songs, Bob three and Eve two. Additionally the Key field in this example may also have a temporal dimension such that we can infer the order in which songs were played.

The only required property of the identifier is that it be consistent over the records we wish to track. So if we change the above identifiers to their SHA-256 representations ("Alice" becomes 3bc51062973c458d5a6f2d8d64a023246354ad7e064b1e4e009ec8a0699a3043 ) we do not compromise our ability to track the behaviour of a user over that data set:

Key UserID (SHA-256 hashed) Artist
1 3bc5106...0699a3043 Queen
2 3bc5106...0699a3043 Queen
6 3bc5106...0699a3043 Queen

We can still make the same anlayses: 3bc...3043 likes Queen and played songs from that band three times. We have however obfuscated the user identifier, assuming that the user identifier had any meaning in the first place.

This latter point is important to note as it depends upon how we interpret the identifier. For example: 3bc5106...99a3043 has no "meaning" other than it being something we use to track over. The string "Alice" may have a meaning..."Alice" as 5 ASCII or Unicode characters are just as meaningful as our hashed value above. However "Alice" itself according to the typing information and usage in the data set is the identifier of the user in some system. Furthermore according to some interpretations "Alice" is a female name and this particular interpretation of this identifier's meaning might have additional impact.

In the above case we stated nothing about whether the strings "Alice", "Bob" and "Eve" actually were people's names nor whether these were linkable to real and unique people.We never really stated the semantics of the UserID field quite deliberately.

An example we can use to demonstrate this is that of the common practice of email-as-identifier. You can use your email address instead of (or as a) user name in  Facebook, G+ and other services. The following string can be interpreted in a number of (potentially) simultaneous ways:

zarquon.123@somesite.zyx
  • a string of 25 ASCII characters
  • an email address of a person/company/entity
  • a user ID for some service
  • a unique identifier linkable to a real person
and so on...

From a tracking point of view, "zarquon.123@somesite.zyx" has just as much meaning as "Alice" or "3bc5106...0699a3043" etc.

We however are now moving into the interpretation of the contents of a field and the semantics beyond that of an identifier which itself is independent of the actual form of the identifier itself. This leads us to the notion of linkability which we shall discuss later.

Tracking as we have hinted can be made more sophisticated through the addition of other identifiers such as IP addresses, device identifiers etc but this just makes the partitioning of the data set more complex and expand the possible internal cross-correlations but doesn't change the basic principle of tracking.

Some identifiers are more useful than others and much of this depends upon how linkable an identifier is to a person or device. For example, device identifiers such as IMEI are particularly useful, email addresses link to persons, IP addresses link to sometimes single computer or devices, sometimes multiple and can also be mapped to locations through the process of geolocation.

So that very briefly introduces what tracking is: simply the ability to correlate and collate sets of data together. The next step is to perform specific analyses over that data and to map those results back to the business and customer.

Really teaching privacy

I'm often called to give tutorials on privacy - usually as part of the audit of some system. It is clear to me that our friends on the legal and consumer advocacy side of things have a monopoly in educating our developers. However this is quite a gulf between these communities and the architects, designers, developers and programmers who have to build systems conforming to privacy requirements.

So, I'm going to write a small set of tutorials focusing on various aspects of privacy from a more technical perspective.

I've written before on what we need to cover, at least from an academic perspective, now after much working at the coal face with R&D teams, it is time to actually get some of this written down.

Watch this space...

Friday, 4 January 2013

Nouvelle cuisine meets big data?

After the post Christmas/holidays eating binge and the inevitable New Year's resolution of dieting, it seems like this article that appears in the Visual Business Intelligence blog by Stephen Few is more than a little apt.

An analogy is made between the fast food and slow food movements (hence the 'apt' earlier) and he article presents the argument that taking a much more measured, "slower" approach to data collection is the way forward.

As the slow food movement emphasizes the preparation, cooking, eating and enjoyment of food (as opposed to the idea of fast food), slow data emphasizes the same when collecting, storing, processing and analysing data. Given the rush to collect as much data as possible with often scant regard to the content, identification and value I can see the appeal of this. Regarding this latter point, an article in The Register: Craptastic analysis turns 2.8 zettabytes of Big Data into 2.8 ZB of FAIL - dramatically explains this.

Taking a moment to really think about what we are gathering, why we are gathering and what we intend to do with the data, other than the attempt construct the perfect advertisement, then we will see that we actually need very little data. This is almost an antithesis to the 'capture and collect everything everywhere just in case we might need it later' approach.

And then with that carefully chosen, semantically well-defined data we are able to process and analyse and enjoy the results of our analysis. The enjoyment of data here being that what is understood from the data and that this understand be more relevant and useful to our business and to our customers.

Taking a slow approach to digesting our data has a number of other side-effects, a few being that the amount of data we store is less, the amount of analytical infrastructure will be less and the value to the consumer (and the business) will be significantly greater as we will not have to sift through billions of uninteresting and irrelevant data-points. The effects upon areas such as privacy should be self-explanatory...indeed isn't this the true goal of the privacy advocates?

A slow data approach might just solve many of the issues we see with data: semantics, isolation, privacy, data storage, analytics, just to mention a few.

Indeed as the slow food movement has as its objectives to enjoy food, so slow data might just be the way through which we appreciate the information, knowledge and wisdom in our big data.

Are we in effect embodying the ideals of nouvelle cuisine as applied to data? A rejection of excessive complication, reducing the processing to preserve the natural information content, the freshest and best possible ingredients, smaller data sets, modern processing techniques, innovation and invention as being drivens because of the data collection (and not because they might happen if we collect data) - the analogies between slow food, nouvelle cuisine and slow data are abundant.

Food for thought...almost literally.

Tuesday, 18 December 2012

Code is Law, Inherent Privacy and a Few Uncomfortable Issues

Lawrence Lessig stated that "code is law" - a maxim that above all should be the most critical in software engineering, especially when put in the context of implementing privacy and security.

I want to talk about some issues that worry me slightly (ok, a lot!). The first is that despite of policies, laws etc, the final implementation of anything related with privacy is in the code the programmers write. The second is that we are building our compliance programmes upon grand schemes and policies and paying piecemeal attention to the actual act of software engineering. The latter we attempt to wrap up in processes and "big ideas", for example, Privacy by Design.

Now before the PbD people get too upset, there's nothing wrong with stating and enumerating your principles, the Agile Manifesto is a great example of this, however there is no doubt that many implementation of agile are poor at best and grossly negligent and destructive at worst. The term used is "technical debt".

Aside: the best people I've seen conduct software development in an agile manner are formal methods people...I guess due to the discipline and training in the fundamentals they've received. This also applied to experienced architects, engineers and programmers for whom much of this formality is second nature.

Addressing the first point: no matter how many policies or great consumer advocates or promises you make, at the end of the day, privacy must be engineered into the architecture, design and code of your systems. It does not matter many powerpoint slides or policy documents or webpages your write, unless the programmers "get it", you can forget privacy, period!

Aside: Banning powerpoint may not be such a bad idea....

Herein lies a problem, the very nature of privacy in your systems means that it crosscuts every aspects of your design and ultimately your whole information strategy. Most of these things do not obviously manifest themselves in the design and code of your systems.

To solve this there must be a fundamental shift from the consumer advocacy-legal focus of privacy to a much deeper, technical or engineering, even scientific approach. This however does not just mean focusing on the design and code, though that is fundamental to the implementation, but to the whole stack of management and strategy from the highest directors to the programmers.

I've seen efforts in this direction but stop at the product management - "Hey, here are the privacy requirements - implement them!" ... which does feel good in that you are interacting, or believe that you are interacting, with the products you are producing but still not sufficiently with the people who really build these. Just producing requirements doesn't help: you need that interaction and communication right across the company.

Of course all of the above is extremely difficult and leads us to our next point which is how we build our compliance programmes in the first place. The simple question here is "are you fully inclusive?", meaning do you include programmers, architects (technical people with everyday experience) or is the programme run by non-technical, or formerly technical staff? Invariably it is the latter.

Compliance programmes must be inclusive otherwise the necessary inherency required to successfully and sufficiently implement the ideas and strategies of that programme will be lost - usually in a sea of powerpoint and policy documents.

Firstly in order to achieve inherent privacy (or security, or xyz) focus must lie on onboarding and educating the programmers, the designers and the architects and less focus on the management, prescription and consumer advocacy. Secondly, any compliance programme must be inclusive and understand the needs of the said technical staff. Thirdly, the engineering and technical staff are the most critical components in your organisation.

Compliance programmes are often measured on the amount of documentation produced (number of slides even?), however this ends up with a self feeding process where for the compliance programme to survive it needs to keep the fear of non-compliance at the fore. Read Jeff Jarvis' article on Privacy Inc.: Scare and Sell and then Jim Adler's talk about PII2012 on The Emergent Privacy-Industrial Complex and you get an idea of what is going wrong. Avoid at all costs creating a privacy priesthood in your compliance programmes.

Aside: This might be good old fashioned economics - if a compliance programme actually worked then there'd be no need for the programme in the end.

There are two interrelated caveats that also need to be discussed, the first of which is that any work in privacy will expose the flaws, holes and crosscutting issues across your products, development programmes and management and engineering skill bases. For example, a request to change a well crafted design to cope with some misunderstood ambiguity in privacy policy is going to end in tears for all concerned. It will demand of management, engineering and your compliance programme a much deeper [scientific] knowledge of what information your products are using, carrying, collecting and processing - to a degree uncommonly found in current practices.

The fundamental knowledge require to really appreciate information management and privacy is extensive and complex. Awareness courses are a start but I've seen precious few courses even attempting to cover the subject of privacy from a technical perspective.

Secondly, privacy will force you to examine your information strategy - or even create and information strategy - and ask very awkward and uncomfortable questions about your products and goals.