
A collection of discussions, links, stories, news and whatever else I find interesting in the fields of computing, information, science, privacy, semantics, mathematics and so on...
Showing posts with label Safety. Show all posts
Showing posts with label Safety. Show all posts
Tuesday, 15 November 2016
Privacy Engineering for Today - DIMECC Presentation
Here is my presentation from the DIMECC 9th Annual Seminary on Business innovation in Finland.


Wednesday, 2 November 2016
CrIM'16 Keynote on Safety Critical Ideas in Privacy
Here are the slides and a longer presentation as a paper will be available soon:
Friday, 5 August 2016
Privacy Engineering Procedures and Ebola
A seemingly unlikely combination: privacy engineering and ebola, though I guess there are similarities by which viruses spread with how personal data spreads around a company - another time and another study I think.
OK, so what the zark do these things have in common - the answer is via a convoluted path and actually is more related to how we react to an incident: privacy or medical (and we're back to safety-critical systems again).
Bit of background first: I've been reading about Marburg and Ebola recently - both are fascinating (and frightening) themselves, but what is more interesting from a procedural point of view is how they were discovered, researched and ultimately how we as a species react to them.
Now the procedural stuff, the CDC have a response plan for Ebola entitled: Identify, Isolate and Inform: Emergency Department Evaluation and Management for Patients Under Investigation for Ebola Virus Disease.
Worth reading just to understand how the CDC explain how to plan your due diligence - something we're exceptionally bad at in privacy ... we just scream PIA and COMPLIANCE !
The point here is that if privacy engineering is to emerge as a discipline we need to address our culture in how we react to incidents and even react in general. Learning from a discipline that already has to face critical incidents is a good start.
OK, so what the zark do these things have in common - the answer is via a convoluted path and actually is more related to how we react to an incident: privacy or medical (and we're back to safety-critical systems again).
Bit of background first: I've been reading about Marburg and Ebola recently - both are fascinating (and frightening) themselves, but what is more interesting from a procedural point of view is how they were discovered, researched and ultimately how we as a species react to them.
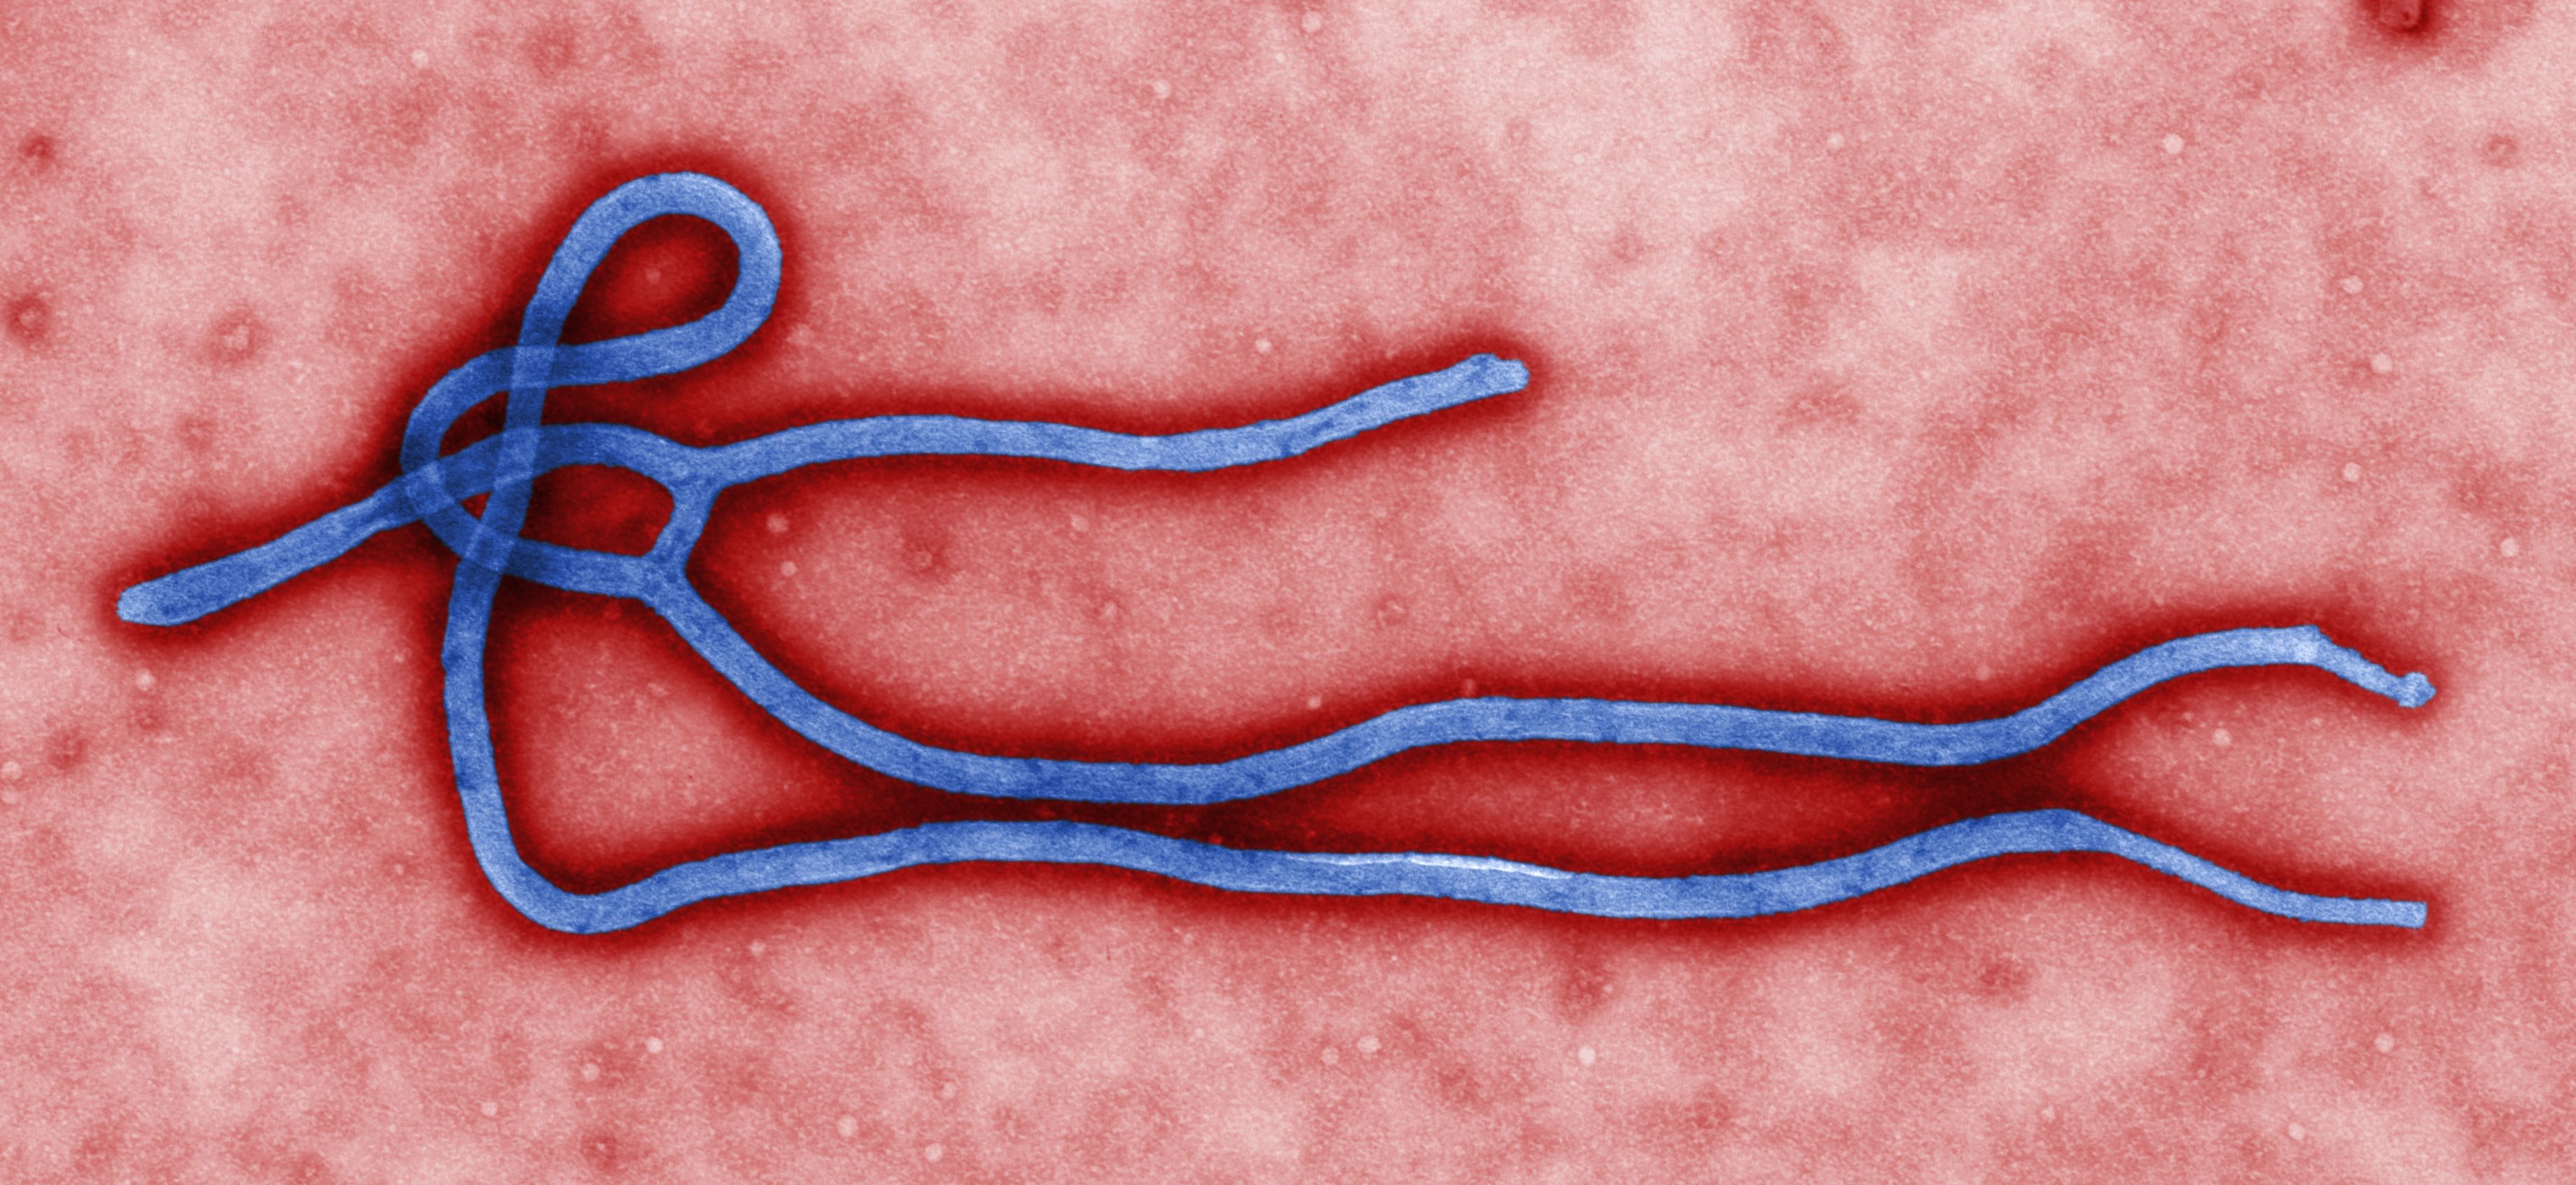 |
| Ebola (via Wikipedia and CDC) |
Worth reading just to understand how the CDC explain how to plan your due diligence - something we're exceptionally bad at in privacy ... we just scream PIA and COMPLIANCE !
The point here is that if privacy engineering is to emerge as a discipline we need to address our culture in how we react to incidents and even react in general. Learning from a discipline that already has to face critical incidents is a good start.
Friday, 23 October 2015
Historial Navigation Techniques in the US Navy
This is an interesting development: a reintroduction of an "historical" technique to ostensibly address a problem introduced by a technology to make things simple(r).
The same techniques guided ancient Polynesians in the open Pacific and led Sir Ernest Shackleton to remote Antarctica, then oriented astronauts when Apollo 12 was disabled by lightning - the techniques of celestial navigation.
A glimmer of the old lore has returned to the Naval Academy.
Officials reinstated brief lessons in celestial navigation this year, nearly two decades after the full class was determined outdated and cut from the curriculum.
That decision, in the late 1990s, made national news and caused a stir among the old guard of navigators.
Maritime nostalgia, however, isn't behind the return.
Rather, the escalating threat of cyberattacks has led the Navy to dust off its tools to measure the angles of stars.
After all, you can't hack a sextant.
Putting the political aspects of the GPS system aside, it is a single point of failure for navigation, at least until Galileo and GLONASS are properly supported by navigation devices. Furthermore, as the article mentions, the GPS system is open to attack from various vectors. The use of "legacy" (I love that word - It doesn't mean obsolete!) technologies such as the sextant address many of these issues.
For me the main thing here is that the sextant forces understanding of navigation - quite literally how coordinates are calculated which is something missing from GPS.
In other words, don't rely upon technology, or if you do, you'd better know how to drop back a level of automation...sounds familiar...it is the basic premise of the 'Children of the Magenta' talk by American Airlines (see here for an earlier blog posting, the video might be available on YouTube somewhere).
In other words, don't rely upon technology, or if you do, you'd better know how to drop back a level of automation...sounds familiar...it is the basic premise of the 'Children of the Magenta' talk by American Airlines (see here for an earlier blog posting, the video might be available on YouTube somewhere).
Tuesday, 17 February 2015
IWPE2015 Keynote
I'm giving the keynote speech at IWPE2015 which is provisionally entitled
I'll talk about some tools and techniques which we can use from other domains such as aviation and medicine and how privacy in software engineering is synonymous with safety in these other domains.
Conference details can be found from an earlier posting or via the link above. Conference date is 21st May 2015 and it will be held in conjunction with the 36th IEEE Symposium on Security and Privacy in San Jose, California.
"Engineering Privacy as a Safety-Critical Concern"
I'll talk about some tools and techniques which we can use from other domains such as aviation and medicine and how privacy in software engineering is synonymous with safety in these other domains.
Conference details can be found from an earlier posting or via the link above. Conference date is 21st May 2015 and it will be held in conjunction with the 36th IEEE Symposium on Security and Privacy in San Jose, California.
Monday, 26 January 2015
Kings Cross,Trains and a Swiss Cheese
New Year's Resolution: write more .... and .... 26 days later....finally got around to it. So after a prolonged break and spending most of it reading upon topics from organizational failures, safety, privacy and a touch of homomorphic encryption, I came around this:
which is an exceptionally well written summary of the problems at King's Cross Railway Station after Christmas 2014 where overrunning engineering works blocked all long distance and commuter rail services out of one of the London busiest termini.
What actually started out as a fantastic opportunity to perform engineering work over a rare, four day holiday became the proverbial nightmare as works overran by 24 hours. As a relatively simple study in the Swiss Cheese model it provides a wealth of issues and examples of how the holes in the Swiss Cheese lined up as a large number of minor problems coalesced into a "disaster".
Despite meticulous planning and well rehearsed contingency and emergency plans, and even pre-emptive measures such as providing extra machinery and fitters to correct problems on-site it eventually came down to a lack of drivers for freight trains that finally provided the final hole in the Safety Swiss Cheese.
An excellent example of how things go wrong despite detailed planning. Of course it is easy to judge with 20/20 hindsight and see clearly that a number of known failure points were obvious, but like many of these cases at each point the situational awareness was for many reasons lacking. Funny how the same aspects occur here in engineering as well as medicine, aviation and of course privacy.
Monday, 13 October 2014
Whiskeygate
No one is really sure who said what and the air is full of denials and the Nuremberg Defense, but it seems like Finland is trying to suppress the word "wisky", or more specifically the Finnish "viski" just in case it corrupt, well, everyone....just think of the children...or maybe it is for my safety and security...but even if it saves just one person...
Yes, this is true:
Anyway Finnish taxes being put to work by our elected and unelected officials...good thing there's nothing else to worry about such as the economy, jobs, overly high taxation, food prices, energy prices, energy dependence, flying squirrels, child benefit reductions hirvikarpaset and a government that wants to avoid all hard decisions at all costs.
After all, banning words, moving kunta boundaries and pay rises of 6000 euros per month are far more important than the people of Finland.
Can anyone say Streisand Effect?
Whisky, Whiskey, Viski, Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski ....
Yes, this is true:
HS: Finnish officials ban the word "whisky" on private blog
Organisers of a beer and whisky fair in Helsinki have been granted a license on condition that search engines do not link to the event’s website when users search for “whisky”, according to a report in Helsingin Sanomat. The officials have also asked the beer and whisky fair to remove the word “whisky” from their logo and the event’s official name.
Anyway Finnish taxes being put to work by our elected and unelected officials...good thing there's nothing else to worry about such as the economy, jobs, overly high taxation, food prices, energy prices, energy dependence, flying squirrels, child benefit reductions hirvikarpaset and a government that wants to avoid all hard decisions at all costs.
After all, banning words, moving kunta boundaries and pay rises of 6000 euros per month are far more important than the people of Finland.
Can anyone say Streisand Effect?
Whisky, Whiskey, Viski, Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski,Whisky, Whiskey, Viski ....
Thursday, 7 August 2014
Privacy and Governance
Actually this is a presentation by Prof. Alastair Scotland of the UK's NHS on governance and, ultimately, patient safety. If you work in governance, privacy, software engineering and any management discipline related with these then this is one video you must watch today.
If it took the NHS 10 years to get this far, then in areas such as privacy which share many of the same characteristics of being a flawed system (in the general sense) with many safety-critical features, we've a huge amount of work to do outside of the mainly philosophical and legal debates about what privacy is.
Alastair Scotland.mp4 from Guy Murray on Vimeo.
Monday, 28 July 2014
Privacy Engineering Book
Privacy Engineering
A dataflow and ontological approach
An essential companion book for those of us who have to model systems from small mobile apps to large, cloudified BigData system from the perspective of privacy and personal data handling.
Available via Amazon (US, UK and all Amazon worldwide sites), CreateSpace and selected bookstores such as Barnes and Noble. Kindle version available, also with Kindle Match Book enabling you to the Kindle version for just 2.99USD when purchasing the paperback.

- Introduction
- Case Study
- Privacy Engineering Process Structure
- Data Flow Modelling
- Security and Information Classifications
- Additional Classification Structures
- Requirements
- Risk and Assessments
- Notice and Consent
- Privacy Enhancing Techniques
- Auditing and Inspections
- Developing a Privacy Programme
Only through properly modelling the system under development can we full appreciate the complexity of where personal data and information flows; and more importantly, effectively communicate this. This book presents an approach based upon data flow modelling, coupled with standardised terminological frameworks, classifications and ontologies to properly annotate and describe the flow of information into, out of and across these systems.
Also provided are structures and frameworks for the engineering process, requirements and audits; and even the privacy programme itself, but takes a pragmatic approach and encourages using and modifying the tools and techniques presented as the local context and needs require.
Published July 2014
ISBN-13: 978-1497569713
ISBN-10: 1497569710
264 Pages, B/W on White Paper
ISBN-10: 1497569710
264 Pages, B/W on White Paper
Monday, 12 May 2014
Privacy and Big Data in Medicine
A short article by myself on the subject of privacy in medicine was just published in the web magazine Britain's Nurses. Quite an experience writing for a very different audience than software engineers, but extremely interesting to note the similarities between the domains.
When it comes to privacy, one of the seemingly infinite problems we face is how to develop the techniques, tools and technologies in our respective domains. Here again we have the choice of reinventing the wheel or looking to different domains and use their knowledge and experiences. This latter route is the much preferred but rarely taken.
So for the moment, I'll take the chance to look back on previous articles that draw lessons from other domains:
Domains such as medicine, civil engineering and especially aviation have been through this process and as information rises in value - that is the economic effects of a data breach or loss of consumer confidence - reach levels where companies will figuratively crash, so the need to take in these learnings and treat information handling as any other element in a safety-critical system.
Finally the article I mentioned: Privacy in Digital Health, 12 May 2014, Britain's Nurses
When it comes to privacy, one of the seemingly infinite problems we face is how to develop the techniques, tools and technologies in our respective domains. Here again we have the choice of reinventing the wheel or looking to different domains and use their knowledge and experiences. This latter route is the much preferred but rarely taken.
So for the moment, I'll take the chance to look back on previous articles that draw lessons from other domains:
Finally the article I mentioned: Privacy in Digital Health, 12 May 2014, Britain's Nurses
Thursday, 8 May 2014
Checklists and Design by Contract
One of the problems I am having with checklists is that they are often, or nearly always, confused with processes: "this is the list of steps we have to do and then you tick them off and all is well" mentality. This is probably why in some cases checklists have been renamed "aide memoirs" [1] and why their use and implementation is so misunderstood.
In the case of aviation or the surgical checklists these do not signify whether it is "safe" to take-off or start whatever procedure but as a reminder to the practitioner and supporting team that they have reached a place where they need to check on their status and progress. The decision to go or no-go is not the remit of the checklist. For example, once a checklist is complete a pilot is free to choose whether to take-off or not irrespective of the answers given to the items on the checklist (cf: [2]).
This got me thinking in that there are some similarities to design-by-contract and this could be used to explain checklists better possibly. For example consider the function to take-off (written in pseudo Eiffel fragments [3]):
take-off
-- get the throttle position, brake status etc and spool-up engines
do
....
end
...
can be called whenever, there is no restriction and this is how it was, until an aircraft crash in the 1930's triggered the development of checklists in aviation. So now we have:
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
do
....
end
...
and in more modern aircraft this is supplemented by features to specifically check on the aircraft status
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
do
if flaps < 10 then
soundAlarm
end
....
end
...
or even:
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
flaps > 10
mode = GroundMode
do
....
ensure
mode = FlightMode
end
...
What you actually see are specific checks from the checklists being incorporated into the basic protection mechanisms of the aircraft functionality. This is analogous to what we might see in a process, for example below we can see the implementation of functionality to encode a project approval checklist into some approval function:
approveProject
require
securityReview.status = Completed
privacyReview.statuse= Completed
continuityReview.status = Completed
performanceReview.status = Completed
architecturalReview.status = Completed
do
...
Now we have said nothing about how the particular reviews were actually made or whether the quality of their results were sufficient. This brings us to the next question of the qualitative part of a checklist and deciding what to expose. Here we have three options:
The first is as explained above, the second and third offer us a choice about how we expose and act upon the information gained through the checklist. Consider a privacy or information content review of system, we would hope that specific aspects are specifically required, while others are just warnings:
approveProject
require
...
privacyReviewStatus = Completed
privacyReview.pciData = False
privacyReview.healthData = False
...
do
if privacyReview.dataFlowModelComplete = False then warn("Incomplete DFDs!") end
...
And we can get even more complex and expose more of the checklist contents as necessary.
The main point here is that if we draw an analogy with programming, some aspects of checklists can be more easily explained. Firstly the basic checklist maxim is:
All the items on a checklist MUST be checked.
then we should be in a place to make a decision based on the following "procedure"
References
[1] Great Ormond Street Hospital did this according to one BBC (I think) documentary.
[2] Spanair Flight 5022
In the case of aviation or the surgical checklists these do not signify whether it is "safe" to take-off or start whatever procedure but as a reminder to the practitioner and supporting team that they have reached a place where they need to check on their status and progress. The decision to go or no-go is not the remit of the checklist. For example, once a checklist is complete a pilot is free to choose whether to take-off or not irrespective of the answers given to the items on the checklist (cf: [2]).
This got me thinking in that there are some similarities to design-by-contract and this could be used to explain checklists better possibly. For example consider the function to take-off (written in pseudo Eiffel fragments [3]):
take-off
-- get the throttle position, brake status etc and spool-up engines
do
....
end
...
can be called whenever, there is no restriction and this is how it was, until an aircraft crash in the 1930's triggered the development of checklists in aviation. So now we have:
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
do
....
end
...
and in more modern aircraft this is supplemented by features to specifically check on the aircraft status
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
do
if flaps < 10 then
soundAlarm
end
....
end
...
or even:
take-off
-- get the throttle position, brake status etc and spool-up engines
require
checklist_complete = True
flaps > 10
mode = GroundMode
do
....
ensure
mode = FlightMode
end
...
What you actually see are specific checks from the checklists being incorporated into the basic protection mechanisms of the aircraft functionality. This is analogous to what we might see in a process, for example below we can see the implementation of functionality to encode a project approval checklist into some approval function:
approveProject
require
securityReview.status = Completed
privacyReview.statuse= Completed
continuityReview.status = Completed
performanceReview.status = Completed
architecturalReview.status = Completed
do
...
Now we have said nothing about how the particular reviews were actually made or whether the quality of their results were sufficient. This brings us to the next question of the qualitative part of a checklist and deciding what to expose. Here we have three options:
- completion
- warnings
- show stopping preconditions
The first is as explained above, the second and third offer us a choice about how we expose and act upon the information gained through the checklist. Consider a privacy or information content review of system, we would hope that specific aspects are specifically required, while others are just warnings:
approveProject
require
...
privacyReviewStatus = Completed
privacyReview.pciData = False
privacyReview.healthData = False
...
do
if privacyReview.dataFlowModelComplete = False then warn("Incomplete DFDs!") end
...
And we can get even more complex and expose more of the checklist contents as necessary.
The main point here is that if we draw an analogy with programming, some aspects of checklists can be more easily explained. Firstly the basic checklist maxim is:
All the items on a checklist MUST be checked.
then we should be in a place to make a decision based on the following "procedure"
- Are all individual items in their respective parameter boundaries?
- Are all the parameters taken as a whole indicating that we are in a state that is considered to be within our definition of "safe" to proceed to the next state?
- Final question: Go or No-Go based on what we know from the two questions above?
Of course, we have glossed over some of the practical implementations and cultural aspects such as team work, decision making and cross-referencing, but what we have described is some of the philosophy and implementation of checklists in a more familiar to some programming context.
References
[1] Great Ormond Street Hospital did this according to one BBC (I think) documentary.
[2] Spanair Flight 5022
Thursday, 27 March 2014
Privacy Checklists and a Study in Ontario
Not that particular study in Ontario, but another in Ontario regarding the Surgical Checklist and its "ineffectiveness", which was rebutted by many including Atul Gwande which ended with this quote:
Relating this back to my experiences in deploying and using checklists for privacy is that THEY ARE NOT A TOOL FOR IMPROVING PRIVACY DIRECTLY but a TOOL for organising your workflows, your actions and ensuring that all members of a team are actively cross-checking each other; and even then this is just a small part of the overall effect. Let us for a moment rewrite Gwande's statement a little:
In the paper [1] (emphasis mine)
Perhaps, however, this study will prompt greater attention to a fundamentally important question for health care reform broadly: how you implement an even simple change in systems that reduces errors and mortality – like a checklist. For there is one thing we know for sure: if you don’t use it, it doesn’t work.
Relating this back to my experiences in deploying and using checklists for privacy is that THEY ARE NOT A TOOL FOR IMPROVING PRIVACY DIRECTLY but a TOOL for organising your workflows, your actions and ensuring that all members of a team are actively cross-checking each other; and even then this is just a small part of the overall effect. Let us for a moment rewrite Gwande's statement a little:
Perhaps, however, this study will prompt greater attention to a fundamentally important question for privacy engineering: how you implement an even simple change in systems that reduces errors and non compliance– like a checklist. For there is one thing we know for sure: if you don’t use it, it doesn’t work.
In the paper [1] (emphasis mine)
The checklist approach to privacy protection has been debated.[24] Checklists have become important safety elements in airplane and medical procedures and are quite common in security auditing. However, their utility for privacy remains questionable. It might be possible to design privacy checklists for frequent and standardized use cases, but the breadth of potential projects makes a standard checklist for everything an unlikely tool.
[24] Ian Oliver, “Safety Systems – Defining Moments” Available at http://ijosblog.blogspot.com/2013/07/systems-safety-defining-moments.html
Indeed the two paragraphs on checklists and privacy impact assessments fails to properly understand the former and compares it against the latter which is a different kind of tool altogether. In fact, a PIA should be done and this would be ensured or reminded by having it included as a point on a checklist for privacy.
Indeed no mention was made, nor has been made of any "standardised checklist". In fact there is a capitalised statement on the bottom of the checklist:
THIS CHECKLIST IS NOT INTENDED TO BE COMPREHENSIVE. ADDITIONS AND MODIFICATIONS TO FIT LOCAL PRACTICE ARE ENCOURAGED.Which can be read about in this article published back in February.
The point here in both cases: surgical and privacy engineering is that the checklist needs to be accompanied by a procedural and "societal" change for it be successful. One only needs to read about Pronovost's work with a simple checklist and the changes surrounding that to understand how checklists work in practice - that and the other experiences presented in Gawande's excellent book on the subject: The Checklist Manifesto. Our experiences can be read about in the presentation Flying Planes, Surgery and Privacy.
* * *
References:
[1] Cavoukian, Cronk, Shapiro (2014) Privacy Engineering: Proactively Embedding Privacy, by Design
Monday, 17 March 2014
Structuring Privacy Requirements pt 1
One of the toughest problems I'm having to solve, not just for my book on privacy engineering, but in my daily job as well is to formulate a set of privacy requirements to the software engineers and the R&D teams.
Actually it isn't that the privacy requirements themselves are hard, we've plenty at the policy level and extrapolating these down into the more functional and security related requirements at the implementation level (ok, it is difficult but there are harder things in this area).
Placing all these in a structure that ties together the various classifications and aspects of information, data flow modelling, requirements and risk management has been interesting and fiendishly difficult to say the least. Getting this structure into a state that supports all of these and getting the semantics of the kinds of thing it is structuring is critical to understanding how all of this privacy engineering works.
We assume that we understand the classification systems, for example the almost traditional Secret-Confidential-Public style security classifications and the Location, Time etc classifications of information type; as well as the other aspects such as purpose, usage, provenance, identity etc. Each of these has its own set of classification elements, hierarchy and other ontological structure. For example for information type:
We also assume we understand data flow modelling with its processes, flows, sources, sinks and logical partitionings. We can also already see the link between elements here (as shown below) and the classification systems above
Now the structure of our requirements needs to take into consideration the various elements from the classification systems, the aspect of the requirement we want to describe (more on this below) and the required detail of requirement relevant to the stage in the software process. This gives us the structure below:

So if we wish to find the requirements for User's Home Address Policy for Local Storage then we take the point corresponding to those coordinates. If there happens to be nothing there then we can use the classification systems' hierarchies to look for the requirement corresponding to a parent; a "user's home address" is-a "Location":
So if we take the example data flow from earlier then for each of the flows, storages and processes we can construct a set of requirements simply by reading off the corresponding requirements from the structure above.
This leads to an interesting situations where it is possible to construct a set of requirements which are overconstraining. That is simply that we can not build a system that can support everything, for example, one data point might trigger a secret classification and key management, encrypted content etc.
We then need to weaken the requirements such that a system can be constructed according to some economic(!) model. As we weaken or retrench our requirements we are introducing risk into the system,
Aside: Retrenchment - here's a good reference: Banach, Poppleton. Controlling Control Systems: An Application of Evolving Retrenchment. ZB 2002:Formal Specification and Development in Z and BLecture Notes in Computer Science Volume 2272, 2002, pp 42-61.
This gives us our link to risk management and deciding whether each "weakness" we introduce is worth the risk. And as risk can be quantified and we can perform further tasks such as failure mode and effects analysis then we obtain a rigorous method to predict failures and make informed decisions about these. I'll describe more on this in later articles.
Actually it isn't that the privacy requirements themselves are hard, we've plenty at the policy level and extrapolating these down into the more functional and security related requirements at the implementation level (ok, it is difficult but there are harder things in this area).
Placing all these in a structure that ties together the various classifications and aspects of information, data flow modelling, requirements and risk management has been interesting and fiendishly difficult to say the least. Getting this structure into a state that supports all of these and getting the semantics of the kinds of thing it is structuring is critical to understanding how all of this privacy engineering works.
We assume that we understand the classification systems, for example the almost traditional Secret-Confidential-Public style security classifications and the Location, Time etc classifications of information type; as well as the other aspects such as purpose, usage, provenance, identity etc. Each of these has its own set of classification elements, hierarchy and other ontological structure. For example for information type:
 |
| Information Type Hierarchy |
 |
| Example Data Flow with Annotations from Previously Described Ontologies/Classification Systems |
So if we wish to find the requirements for User's Home Address Policy for Local Storage then we take the point corresponding to those coordinates. If there happens to be nothing there then we can use the classification systems' hierarchies to look for the requirement corresponding to a parent; a "user's home address" is-a "Location":
This leads to an interesting situations where it is possible to construct a set of requirements which are overconstraining. That is simply that we can not build a system that can support everything, for example, one data point might trigger a secret classification and key management, encrypted content etc.
We then need to weaken the requirements such that a system can be constructed according to some economic(!) model. As we weaken or retrench our requirements we are introducing risk into the system,
Aside: Retrenchment - here's a good reference: Banach, Poppleton. Controlling Control Systems: An Application of Evolving Retrenchment. ZB 2002:Formal Specification and Development in Z and BLecture Notes in Computer Science Volume 2272, 2002, pp 42-61.
This gives us our link to risk management and deciding whether each "weakness" we introduce is worth the risk. And as risk can be quantified and we can perform further tasks such as failure mode and effects analysis then we obtain a rigorous method to predict failures and make informed decisions about these. I'll describe more on this in later articles.
Thursday, 23 January 2014
On being formal, and possibly agile too...
Way back in my past I used to research formal methods for software engineering. Actually I still do, though now most of my time is actually using formal methods to make better software.
Formal methods are nothing more than a collection of languages and techniques for modifying and reasoning about things (models) written in those languages. Some of these techniques encompass how the process of building a system is made. Herein lies one of the first problems encountered by formal methods practitioners and that is the almost constant challenge from some, such as many in the agile community, that seem to be religiously against any form of modelling.
To those who believe that code is the only deliverable and the only thing that matters, well, C++, C, Fortran, Clojure etc are all formal languages, and you're probably using many of the techniques from formal methods right now as your write your code.
Language such as B, Alloy, Z, VDM etc do is provide a method of expressing a model without worrying about certain, awkward details of their implementation or execution.
Indeed what is happening here is that we have languages and techniques that allow you to concentrate on reasoning and thinking about the problem you are trying to solve without getting bogged down in the details of the final implementation.
If your first worry is the implementation language, or the operating system, or which libraries to use, etc, then you're most certainly not solving the problem.
At Nokia we had some very great successes using formal methods in an agile manner for the development of a semantic web infrastructure for the "Internet of Things". Concentrating on what the system had to do and then later worrying about how it was implemented meant that when it did come to the time we needed to architect the components and decide on specific implementation issues we already knew how the system was going to work, what tests we would need to run and what the expected answers were going to be.
Indeed, many of the tests were little more than checking that the code behaved the same as our earlier models - regression testing if you like.
This resulted in a huge decrease in the time spent in coding and the effective removal of nearly all (logic) bugs before even the beta releases. In fact most of the bugs turned out to by typos.
Furthermore, when it came to updating the software with additional features, instead of blindly bolting on a new use case we could reduce most of the new feature requests down to library or convenience functions over the core functionality rather than complicating the design with those "new" features.
This latter point is very important in that even though there is pressure to constantly add new features (and the Pareto Principle applies here), most new features are really just convenience functions that already exist in the software.
I even remember one system where management demanded so many new features (all specified as their own use cases) that the system actually ended up implementing not only the same feature many times but features to disable the requested feature...
Ultimately formal methods is a discipline of thinking, rather than any technique to develop software. Just as much as Agile is a discipline of development.
To use formal methods does not mean any form of top-down or Waterfall development, it does not mean that one has to use refinement or a language like B or Z or VDM or Alloy etc. Just the simple act of writing a precondition to a function in C, or expressing a simple class diagram in UML, or ER diagram to explain a database schema (SQL or NoSQL) to demonstrate the workings of a system, or to clarify what something mean IS being formal.
The best agile developers I have seen all have formal methods backgrounds. The reasoning is that they already have the discipline and education and the tools to think and reason about their system, even if applied implicitly. Agile depends upon great communication between the developers and the customers and giving those customers exactly what they need in a manner that avoids technical debt (viz. situational awareness).
Whether we like it or not, great software engineering comes from understanding how our craft works at its most fundamental levels - imagine civil engineering without the mathematics of physics (a classic example), or even ballet without an understanding of human movement?
References:
[1] Ian Oliver Experiences of Formal Methods in 'Conventional' Software and Systems Design. FACS 2007 Christmas Workshop: Formal Methods in Industry. BCS London, UK, 17 December 2007
[2] Ian Oliver Experiences of Formal Methods in 'Conventional' Software and Systems Design
Tuesday, 19 November 2013
Losing Situational Awareness in Software Engineering
The cause of many aircraft accidents is
attributed to loss of situational awareness. The reasons for such a situation
are generally due to high workload, confusing or incorrect data and
misinterpretation of data by the pilot.
The common manifestation of this is mode
confusion where the pilot's expectation for a given situation (eg: approach)
does not match the actual situation. This is often seen (though not exclusively)
in highly automated environments, leading to the oft repeated anecdote:
A novice pilot will exclaim, "Hey! What's it doing now?", whereas an experienced pilot will exclaim, "Hey! It's doing that again!"
Aside: while this seems to be applied to
Airbus’ FBW models, the above can be traced back to the
American Airlines Childrenof the Magenta tutorial and specifically refers to the decidedly non-FBW Boeing
757/767 and Airbus A300 models, and not the modern computerized machines… [1]
This obviously isn't restricted to
aircraft but also to many other environments; for example, consider the
situation in a car when cruise control is deactivated due to an external
situation not perceived by the driver. Is the car slowing due to road
conditions, braking etc? Consider this in conjunction when you are expecting
the car to slow down where the deactivation has the same effect as expected;
this type of loss of situational awareness was seen in the Turkish 737 accident
at Schipol.
In an auditing environment where we obtain
a view horizontally across a company we too suffer from loss of situational
awareness. In agile, fast environments with many simultaneous projects, we
often fail to see the interactions between those projects.
Yet, understanding these links in
non-functional areas such as security and privacy is absolutely critical to a
clear and consistent application of policy and decisions.
A complicating factor we have seen is
that projects change names, components of projects and data-sets are reused
both dynamically and statically leading to identity confusion. Systems reside
locally, in the cloud and elsewhere in the Universe, terminology is stretched
to illogical extremes: big data and agile being two examples of this. Simplicity is considered a weakness and
complexity a sign of the hero developer and manager.
In systems with safetycritical properties heroes are a bad thing.
In today's so-called agile, uber-innovative,
risk-taking, fail fast, fail often, continuous deployment and development
environments we are missing the very basic and I guess old fashioned exercise
of communicating rigorously and simply what we're doing and reusing material
that already exists.
Fail often, fail fast, keep making the
same mistakes and grow that technical debt.
We need to build platforms around shared
data, not functionality overlapping, vertical components with the siloed data
mentality. This required formal communication and an emphasis on quality, not
on the quantity of rehashing buzzwords from the current zeitgeist.
In major construction projects there is
always a coordinator whose job it is to ensure that not only do individual
experts communicate (eg: the plumbers, the electricians etc) but that their
work is complimentary and that one group does not repeat the work or base that
another team has put in place.
If software engineers built a house, one
team would construct foundations by tearing down the walls that inconveniently stood
atop of already built foundations, while another would build windows and doors
while digging up the foundation as it is being constructed. A further team
charged with installing the plumbing and electrics would first endeavor to
invent copper, water and electricity...and all together losing awareness of the
overall situation.
OK, I'm being hard on my fellow software
engineers, but it is critical that we concentrate more on communication, common
goals, less "competition" [2] and ensuring that our fellow software
engineers are aware of each other's tasks.
As a final example, we will (and have!)
seen situations in big data where analytics is severely compromised because we
failed to communicate and decide upon common data models, common catalogs of
where and what data exists.
So, like the pilot faced with a situation
where he recognises he's losing his situational awareness, drop back down the
automation and resort to flying by the old-fashioned methods and raw data.
The next question is, how do you
recognise that you're losing situational awareness?
Wednesday, 25 September 2013
Data Handling
Organisations hold databases which contain personally identifiable information which if leaked could cause harm to all parties. Here we start to transcend from "security and privacy" as technological functions to "trust", particularly trust that people who have access to the data handle it safely. The maxim that needs to be applied when handling data:
I'd therefore like to briefly describe a number of points on this subject to lay out which areas of focus need to be made. These guides should be adapted to local context and applied regardless of data content, despite how benign the data might appear [1]:
Collection
Note the analogies between handling data and the procedures for handling chemicals in an industrial context or patients in a medical context. Of course, the above guides are just guides and incomplete as we can not foresee every situation and context - local customisation of the implementation of there is always required.
Notes:
[1] The UK's Health and Safety Executive COSHH guidelines on handling water - these might surprise you for a such an "inert" substance, for example: Portable Water and Legionella Control and Hot and Cold Water Systems.
Data handling is a safety-crtical exercise.
I'd therefore like to briefly describe a number of points on this subject to lay out which areas of focus need to be made. These guides should be adapted to local context and applied regardless of data content, despite how benign the data might appear [1]:
Collection
- data collection should be minimised and avoid superfluous, unnecessary datapoints. In particular data pertaining to race, ethniticty, health, sexual persuasion and politics are to be avoided except in certain well-defined cases such as personel records or particular kinds of ethnographic research.
- be aware of the possibilities of cross-referencing the data and the accuracy at which certain data points can be collected, eg: street name vs GPS coördinates
- the data subject must be informed about the collection of any personal details
- be clear for what purposes and usages this data is being collected and stick to those purposes and usages
- the storage of the data must have the necessary, relevant protections in place such as encryption at file system, database and/or field level as necessary
- be aware of the location of the storage and whether this is in-house or in-cloud. Certain jurisdictions take a dim view of data leaving their countries for example
- data in transit should be over secure medium and/or encrypted
- emailing or moving data by physical media is as much transmission of data as is downloading via web browser and the like
- be very, very careful about using email, instant messaging and other common messaging systems. Some systems support security classification and encryption, be sure to know how and when to use those mechanisms. Even internal company email is not secure!
- data deletion should always be made to appropriate standards such as that detailed in the DoD 5220.22-M and AFSSI-5020 standards
- if data is deleted then ensure that certifcates of destruction for the data and any hardware including backups is obtained
- virtual machines, "cloud" and hosted services are always problematic - only use those which have a detailed and sufficient data deletion procedures
- don't forget about email archives, backup devices, "forgotten" memory sticks, cameras etc...
- all data must be assessed for its sensitivity and marked appropriately
- a simple Secret-Confidential-Public-Unclassified system suffices with approriate defined requirements for each level
- further classification such as content marking may also be employed
- ensure that everyone knows what these clasifications mean
- only persons who have a need to view and hold the data are given access
- access control here is primarly a back-office procedure which may have a technical implementation
- auditing a logging of accesses, grants of access and revokations should be made
- a revokation of access must be made as soon as it becomes necessary, eg: someone leaving the company.
- ensure in the above case that any data still held by that person, eg: backups, memory sticks, laptop contents etc is also dealt with
- are you procedures documented sufficiently and in compliance with necessary standards, eg: ISO9000 etc? Even if you don't need to be certified you can still apply good practice!
- when data is extracted from a database ensure that the appropriate security handling, markings and requirements are preserved on the extract. If the database is Secret then so should be all extracts from that data
- extracts should be sanitised - stripped of unnecessary fields - and anonymised/obfuscated as necessary - these processed extracts need to be reclassified!
- a safe environment is one where the above security controls can be enforced, eg: a company's intranet, and even here the movement of data by phsyical means (memory stick etc) or electronic means (emails) must be minimised
- internal email systems are not necessarily secure
- clean desk and locked office policies may be required in some instances
- can an audit trail of access be established?
- outside of the safe environment, eg: in public, on the train or at conference, precautions must be made to ensure the data remains unavailable to non authorised parties through mechansims such as full disk encryption or file encryption
- use of removable media such as memory sticks should be discouraged
- printing of data similar so, especially when it comes to disposal of printed media
- the data and the handler should not be parted unless it is absolutely necessary, for example, packing the laptop into the checked baggage on an aircraft; and even this situation might not be safe in all cases
- a procedure for handling loss of data needs to be defined
- such a procedure needs to establish: the handler, the data set, the media on which the data was stored, the contents, the amount, the time of loss and location. For example, were the company's financial statements for the coming year lost on an unencrypted memory stick on a train late a night versus was an encrypted laptop stolen?
- the necessity to inform authorities (eg: police, data breach announcement) must be established
Note the analogies between handling data and the procedures for handling chemicals in an industrial context or patients in a medical context. Of course, the above guides are just guides and incomplete as we can not foresee every situation and context - local customisation of the implementation of there is always required.
Notes:
[1] The UK's Health and Safety Executive COSHH guidelines on handling water - these might surprise you for a such an "inert" substance, for example: Portable Water and Legionella Control and Hot and Cold Water Systems.
Saturday, 10 August 2013
Flying planes, Surgery and Privacy - the presentation
Here's a version of a talk I gave with a colleague on our experiences in using checklists in our daily work auditing systems for privacy compliance. To me the surgical checklist is probably the most apt for the types of work we perform during a privacy audit. Then privacy steps beyond the bounds of just "privacy" to becoming a more information safety issue:
Monday, 5 August 2013
Understanding Software Engineering Accidents
The cause of 99.999...% of accidents is easy to ascertain, quite
simply it is the pilot's/driver's fault. In the cases of two recent
aviation and railway accidents (Asiana 214 and the Galicia's train crash) these were caused by the pilot and driver respectively....?
Finding the causes of an accident don't actually involve finding who is to blame but rather the whole context of what led up to the point where an accident was inevitable. And then even after that exploring what actually occurred during and after the accident.
The reasoning here is that if we concentrate on who to blame then we will miss all the circumstances that allowed that accident to occur in the first place. For example., in the case of the Galician train crash it has been ascertained that the driver was speeding, on the phone and had a history of breaking the rules. However this misses the more subtle questions of why did the train derail, why could the driver break the speed limit, what was the reasoning of the phone call, why did the carriages fail catastrophically after the derailment, did the safety systems work sufficiently, what state was the signalling in, did the driver override systems, was the driver sufficiently trained etc etc etc.
In other words, the whole context of the systems and organisation needs to be taken into account before appointing final blame; and even then very, very rarely is it single point of failure: the Swiss Cheese Model.
If we apply this model to software engineering and specifically accidents such as hacking and data breaches we become very aware of how many holes in our computing Swiss cheese we have.
Take a simple data breach where "hackers" have accessed a database on some server via an SQL injection via some web pages. If we apply our earlier thinking, it is obviously the fault of the 'stupid' system administrators who can't secure a system and the 'stupid' software engineers who can't write good code. Hindsight is great here isn't it?
To answer 'who to blame?' or better still 'why did things go wrong and how can we prevent this in the future?' we need to put ourselves, as other accident investigators do, in the position of those software engineers, system administrators, architects, hackers and managers AT THE POINT IN TIME WHERE THEY ACTED, and NEVER in hindsight.
Why did the trained, intelligent software engineer write code susceptible to SQLi in the first place?
Maybe they were under time pressure, no proper, formal design documentation, coding standards, never trained to spot those kinds of errors? Actually just stating that we have a failure of discipline is already pointing to wholesale failures across our whole organisation rather than just one individual.
Even if in the above case this was malice by the programmer, then why didn't the testing pick this up? Why was the code released without testing or checking? Now we have a failure elsewhere too.
Were there no procedures for this? Was the code signed-off by management with the risk in place? Now the net widens further across the organisation
and so on...
In aviation there is a term to explain most accidents: loss of situational awareness, which when explored invariably ends up with a multitude of 'wrong' choices being made over a longer period of time rather than just at those few critical minutes or hours in the cockpit.
I'm of the opinion that in software engineering that we almost always operate in a mode where we have no or little situational awareness. Our systems are complex, we lack formal models of our systems that clearly and concisely explain how the system works; indeed one of the maxims used by some practitioners of agile methods actively eschews the use of formality and modelling tools. Coupled with tight deadlines, a code-is-king mentality and rapidly and inconsistently changing requirements we have a fantastic recipe for disaster.
Bringing this back to an aviation analogy again, consider Turkish Airlines Flight 1951 which crashed as Schiphol in 2009. It was initially easy to blame the pilots for allowíng the plane to stall on final approach, but the whole accident investigation revealed deficiencies in the training, the approach procedures of Schiphol, a non-fault tolerant autothrottle and radar combination, a massively high workload situation for the pilots and ultimately a fault which manifested itself in precisely the behaviour that the pilots were requiring and expecting on their approach, that is the aircraft was losing speed.
As an exercise, how does the above accident map to what we experience every day in software engineering? Given high workloads, changing requirements, inconsistent planning and deadlines to get something (anything!) out that sort of works and we start getting answers to why intelligent administrators and programmers make mistakes.
Subscribe to:
Posts (Atom)